> For the complete documentation index, see [llms.txt](https://docs.syntho.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.syntho.ai/setup-workspaces/create-a-workspace/connect-to-a-database/databricks.md).
# Databricks
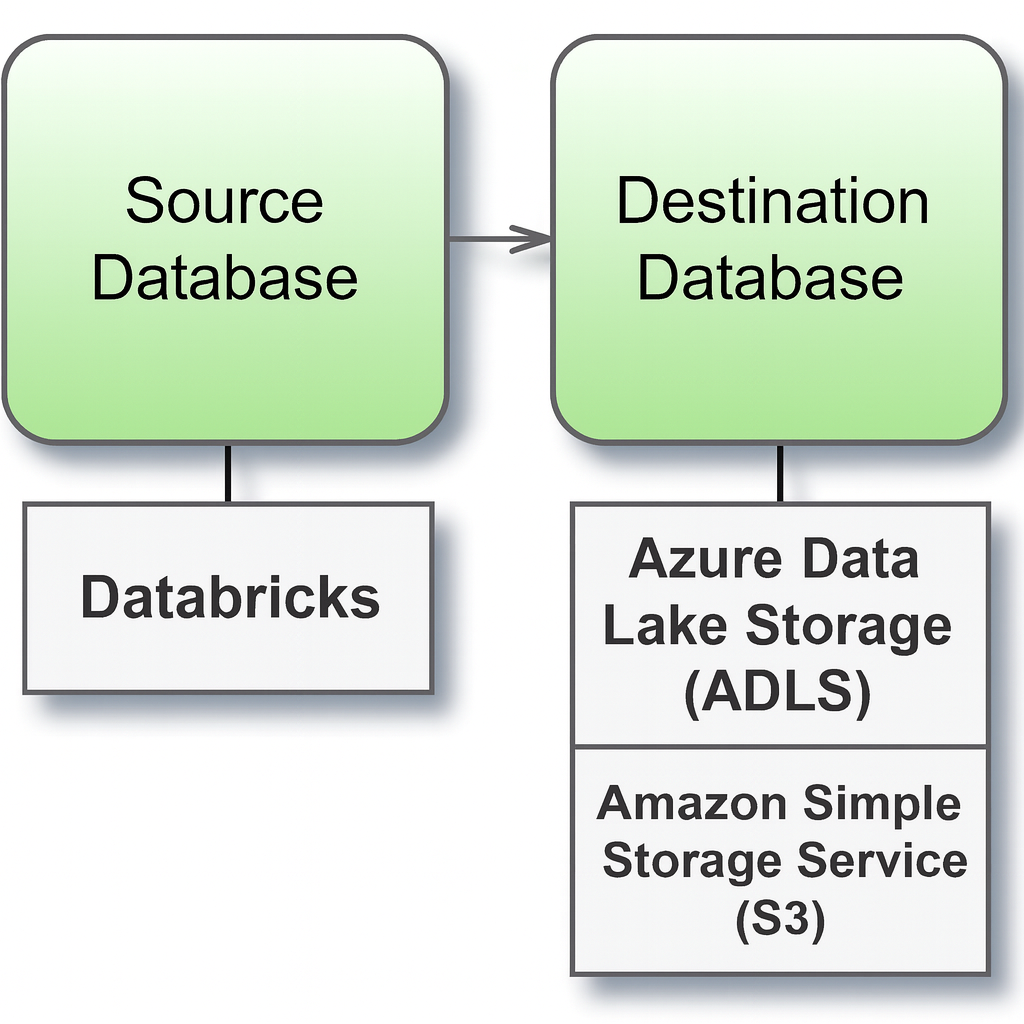
Source and Destination Databases
{% hint style="info" %}
**Important**
This connector can only be used as a source database. The generated data can be written to Local [Filesystem](/setup-workspaces/create-a-workspace/connect-to-a-database/local-filesystem.md), [Azure Data Lake Storage (ADLS)](/setup-workspaces/create-a-workspace/connect-to-a-database/azure-data-lake-storage-adls.md) or [Amazon Simple Storage Service (S3)](/setup-workspaces/create-a-workspace/connect-to-a-database/amazon-simple-storage-service-s3.md) as Parquet files.
{% endhint %}
## Before you begin
Before you begin, gather this connection information:
* Name of the server that hosts the database you want to connect to and port number
* The name of the database that you want to connect to
* HTTP path to the data source
* A Databricks service principal that Syntho can authenticate as through workload identity federation (see [Authentication](#authentication))
* In Databricks, find your cluster server hostname and HTTP path using the instructions in [Construct the JDBC URL](https://docs.databricks.com/user-guide/bi/jdbc-odbc-bi.html#http-path) on the Databricks website.
If you first need to load data into Databricks, see [Importing Data into Databricks](/setup-workspaces/create-a-workspace/connect-to-a-database/databricks/importing-data-into-databricks.md).
## Connect and set up the workspace
1. Launch **Syntho** and select **Connect to a database** (or **Create workspace**).
2. Under **The connection details**, choose **Databricks** from the **Type** dropdown.
3. Fill in the required fields:
* **Server hostname** → e.g. `adb-1111111111111111.0.azuredatabricks.net`
* **Port number** → default is `443`
* **Catalog name** → e.g. `demo_catalog`
* **Database name** → e.g. `marketing_db`
* **HTTP Path** → e.g. `sql/protocolv1/o/1234567890123456/0000-111111-demo123`
* **Warehouse ID (optional)** → the SQL Warehouse to query through (recommended). Use this when possible. It is usually faster and more stable for large databases. If omitted, Syntho falls back to JDBC retrieval via the Spark driver.
* **Service principal client ID (optional)** → the application ID of the service principal to authenticate as, e.g. `d5703d0f-0000-0000-0000-000000000000`. Leave it empty to use the client ID configured in the deployment.
* **Service principal client secret (optional)** → only when the connection authenticates with a client secret instead of workload identity federation. See [Service principal client secret (alternative)](#service-principal-client-secret-alternative).
4. Click **Create Workspace** to complete the setup.\
If Syntho can't make the connection, verify that your credentials are correct. If issues persist, your computer may not be able to locate the server. Contact your **network administrator** or **database administrator** for support.
## Authentication
Syntho authenticates to Databricks with short-lived OAuth tokens through [workload identity federation](https://docs.databricks.com/aws/en/dev-tools/auth/oauth-federation). With federation, Syntho does not store a Databricks secret. If federation is not available in your environment, a connection can use a [service principal client secret](#service-principal-client-secret-alternative) instead. Personal access tokens are not supported.
Each time Syntho connects, it exchanges an identity token for a Databricks access token. Your Kubernetes cluster issues the identity token to Syntho's ServiceAccount and rotates it. Databricks only issues an access token when the identity token matches a federation policy on the service principal. The access token expires after about one hour.
### Configure Databricks
1. Create a service principal in your Databricks account and assign it to the workspace.
2. Create a [federation policy](https://docs.databricks.com/aws/en/dev-tools/auth/oauth-federation-policy) on the service principal:
* **Issuer** → the OIDC issuer URL of your Kubernetes cluster.
* **Audience** → the value configured for Syntho's projected token, for example your Databricks account ID.
* **Subject** → Syntho's ServiceAccount, `system:serviceaccount::`.
* If Databricks cannot reach your cluster's OIDC discovery endpoint, for example for on-premises clusters, provide the cluster's signing keys in the policy as JWKS JSON.
3. Grant the service principal `USE CATALOG`, `USE SCHEMA` and `SELECT` on the source data, and `CAN USE` on the SQL warehouse (or `CAN ATTACH TO` on the cluster).
### Configure Syntho
Syntho connects to Databricks from Core API, its worker and Core (the Ray head and any Ray workers). Each of them needs the identity token and these environment variables (also listed in [Application settings](/deploy-syntho/application-settings.md#databricks-authentication)):
| Name | Description |
| --------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `DATABRICKS_OIDC_TOKEN_FILE` | Path of the identity token file. |
| `DATABRICKS_CLIENT_ID` | Application ID of the service principal. Optional when every connection sets **Service principal client ID**. |
| `SYNTHO_DATABRICKS_ALLOWED_HOSTS` | Optional. Comma-separated workspace hosts that connections may use besides the Databricks cloud domains, for example a custom domain or private endpoint. `*.example.com` allows every subdomain of `example.com`. See [Allowed workspace hosts](#allowed-workspace-hosts). |
#### Kubernetes (Helm)
The Syntho and Ray Helm charts mount a projected ServiceAccount token, which Kubernetes issues and rotates. The steps below change your own values files, the ones you pass to Helm with `--values` (commonly `helm/syntho-ui/values.yaml` and `helm/ray/values.yaml`). Don't edit the `values.yaml` files inside the charts.
1. Choose the name of the ServiceAccount that Syntho runs as, for example `syntho`. The Syntho chart creates it in step 3. Its name and namespace make up the subject of the federation policy, here `system:serviceaccount:syntho:syntho`.
2. Find the issuer of your cluster for the federation policy:
```bash
kubectl get --raw /.well-known/openid-configuration | jq -r .issuer
```
If Databricks cannot reach that issuer, add the cluster's signing keys to the policy as JWKS JSON:
```bash
kubectl get --raw /openid/v1/jwks
```
Update the policy when your cluster rotates its signing keys.
3. In your Syntho chart values, name the ServiceAccount and enable workload identity. Core API and its worker then mount the token and get the environment variables:
```yaml
serviceAccount:
create: true
name: syntho
databricks:
workloadIdentity:
enabled: true
audience:
clientId:
```
Without `name`, the chart names the ServiceAccount after the release, for example `syntho-ui`. Setting `name` on an existing installation replaces that ServiceAccount and restarts Core API and its worker.
If you prefer to manage the ServiceAccount yourself, create it with `kubectl create serviceaccount syntho --namespace syntho` and set `create: false`.
4. In your Ray chart values, configure the Ray head under `ray-cluster`. The Ray chart has no switch for this, so set the ServiceAccount, environment variables and token volume yourself. Use the same audience and client ID as in step 3.
Helm replaces lists instead of merging them, so `volumes` and `volumeMounts` must repeat the chart's default entries; otherwise Ray loses its storage. If you already set `containerEnv`, `volumes` or `volumeMounts` for the head, add the new entries to your lists. A complete Ray values file looks like this:
```yaml
SynthoLicense:
kuberay-operator:
imagePullSecrets:
- name: syntho-cr-secret
ray-operator:
imagePullSecrets:
- name: syntho-cr-secret
ray-cluster:
imagePullSecrets:
- name: syntho-cr-secret
image:
tag:
head:
serviceAccountName: syntho
containerEnv:
- name: DATABRICKS_OIDC_TOKEN_FILE
value: /var/run/secrets/syntho/databricks/token
- name: DATABRICKS_CLIENT_ID
value:
volumes:
# Defaults of the chart
- name: log-volume
emptyDir: {}
- name: ray-workflows
persistentVolumeClaim:
claimName: ray-workflows-claim
- name: ray-data
persistentVolumeClaim:
claimName: ray-data-claim
# Databricks identity token
- name: databricks-token
projected:
sources:
- serviceAccountToken:
path: token
audience:
expirationSeconds: 3600
volumeMounts:
# Defaults of the chart
- mountPath: /tmp/ray
name: log-volume
- mountPath: /tmp/ray-workflows
name: ray-workflows
- mountPath: /tmp/ray-data
name: ray-data
# Databricks identity token
- name: databricks-token
mountPath: /var/run/secrets/syntho/databricks
readOnly: true
```
By default no Ray workers run. If you run workers, through `worker` or a group under `additionalWorkerGroups`, give that group the same `serviceAccountName`, `containerEnv`, `volumes` and `volumeMounts`.
5. Deploy both charts as described in [Deploy Syntho using Kubernetes](/deploy-syntho/deploy-syntho-using-kubernetes.md). The Ray head can't start until the Syntho chart has created the ServiceAccount, so deploy the Syntho chart first or expect the Ray head to start shortly after it.
On an existing installation, KubeRay doesn't recreate the Ray head when its configuration changes. After upgrading both charts, recreate it:
```bash
kubectl -n syntho delete pod -l ray.io/node-type=head
```
6. Check that Core API, its worker and the Ray head have the identity token. Each command prints a token:
```bash
kubectl -n syntho exec deploy/core -- cat /var/run/secrets/syntho/databricks/token
kubectl -n syntho exec deploy/core-worker -- cat /var/run/secrets/syntho/databricks/token
kubectl -n syntho exec "$(kubectl -n syntho get pod -l ray.io/node-type=head -o name)" -- cat /var/run/secrets/syntho/databricks/token
```
7. Test a Databricks connection in Syntho.
#### GitOps tools (Argo CD, Flux)
When a GitOps tool deploys the charts, the values are the same as in [Kubernetes (Helm)](#kubernetes-helm); only where you keep them changes.
* **Values:** keep the Syntho and Ray values files from steps 3 and 4 in your configuration repository and reference them from the tool. With Argo CD, use `valueFiles` in a multi-source Application (Argo CD 2.6 or later), or put the values inline under `helm.valuesObject`. With Flux, use `values` or `valuesFrom` in the `HelmRelease`. The tool renders the charts with Helm, so lists are still replaced, not merged.
* **ServiceAccount:** the Syntho chart creates it, so the Ray head starts once the Syntho chart is synced. To start the Ray head only after that, sync the Syntho Application first, for example with sync waves in an app of apps, or a Flux `dependsOn` on the Syntho `HelmRelease`. If you manage the ServiceAccount yourself instead (`serviceAccount.create: false`), commit it as a manifest that syncs before both charts:
```yaml
apiVersion: v1
kind: ServiceAccount
metadata:
name: syntho
namespace: syntho
annotations:
argocd.argoproj.io/sync-wave: "-1"
```
* **Ray head on upgrades:** KubeRay doesn't recreate the Ray head when the Ray chart changes, so a sync doesn't apply the new values to it. Delete the Ray head pod after the sync, as in step 5.
For example, an Argo CD Application for the Ray chart that reads its values from your configuration repository:
```yaml
apiVersion: argoproj.io/v1alpha1
kind: Application
metadata:
name: ray-cluster
namespace: argocd
spec:
project: default
destination:
server: https://kubernetes.default.svc
namespace: syntho
sources:
- repoURL:
path: helm/ray/chart
targetRevision:
helm:
valueFiles:
- $values/syntho/ray-values.yaml
- repoURL:
targetRevision: main
ref: values
```
#### Docker Compose
For Docker Compose deployments, we recommend a [service principal client secret](#service-principal-client-secret-alternative). Docker Compose has no platform that issues and rotates identity tokens, so federation needs infrastructure that you run yourself. The client secret is entered on each connection, so the Docker Compose files and `.env` need no changes.
To use workload identity federation with Docker Compose anyway:
1. Obtain identity tokens for Syntho from an identity provider that the federation policy trusts, and write them to a file on the host. Run your own process to replace the token before it expires.
2. Mount the directory that contains the file read-only into the `core`, `core-api` and `core-api-worker` services, for example in a `docker-compose.override.yaml`:
```yaml
services:
core:
volumes:
- /path/on/host/databricks:/var/run/secrets/syntho/databricks:ro
core-api:
volumes:
- /path/on/host/databricks:/var/run/secrets/syntho/databricks:ro
core-api-worker:
volumes:
- /path/on/host/databricks:/var/run/secrets/syntho/databricks:ro
```
Mount the directory, not the file: when the token file is replaced, a file mount keeps showing the old token.
3. Add the variables to the `.env` file of the deployment. The `core`, `core-api` and `core-api-worker` services all read it:
```bash
DATABRICKS_OIDC_TOKEN_FILE=/var/run/secrets/syntho/databricks/token
DATABRICKS_CLIENT_ID=
```
4. Restart the deployment with `docker compose up -d` and test a Databricks connection in Syntho.
### Allowed workspace hosts
Syntho only sends credentials over HTTPS to hosts in the Databricks cloud domains: `*.cloud.databricks.com`, `*.cloud.databricks.us`, `*.azuredatabricks.net`, `*.databricks.azure.us`, `*.databricks.azure.cn` and `*.gcp.databricks.com`. Connections to any other host fail with an error on **Server hostname**.
If your workspace is reached through another host, add it to `SYNTHO_DATABRICKS_ALLOWED_HOSTS` on the same services as the other variables. The Databricks cloud domains always stay allowed, for example:
```shell
SYNTHO_DATABRICKS_ALLOWED_HOSTS=databricks.internal.example.com,*.privatelink.example.com
```
Only add hosts you trust: every allowed host receives the identity token or client secret of the connection.
### Security considerations
* **Credentials only go to allowed hosts.** Users choose the host of a connection, so Syntho refuses hosts outside the [allowed workspace hosts](#allowed-workspace-hosts) instead of sending them the identity token or client secret.
* **The client ID and audience are not secrets.** Knowing them is not enough to get a Databricks token. The protection comes from the identity token: it must be signed by your cluster and match the policy's issuer, audience and subject.
* **Keep the subject narrow.** Anyone who can obtain an identity token that matches the policy can act as the service principal. Use a ServiceAccount dedicated to Syntho, and restrict who can run workloads under that ServiceAccount, create tokens for it, or read its projected token.
* **Use a dedicated audience.** Use an audience that only this federation policy accepts, so that tokens Syntho's ServiceAccount gets for other services can't be exchanged for Databricks tokens.
* **Grant the least privilege.** Only grant read access to the data Syntho needs. A service principal also inherits the grants of the groups it belongs to, including the automatic `account users` group. Review what those groups can access.
* **Remove unneeded entitlements.** When connecting through a SQL warehouse, Syntho only needs the `Databricks SQL access` entitlement. Remove the others, such as `Workspace access`, from the service principal.
### Service principal client secret (alternative)
If workload identity federation is not available in your environment, a connection can authenticate with an [OAuth secret of the service principal](https://docs.databricks.com/aws/en/dev-tools/auth/oauth-m2m) instead (OAuth machine-to-machine). Use federation whenever possible: it does not require Syntho to store a secret.
1. Create an OAuth secret for the service principal in your Databricks account, and grant the service principal access as described in [Configure Databricks](#configure-databricks), step 3.
2. In the connection details, fill in:
* **Service principal client ID (optional)** → the application ID of the service principal. Required when using a client secret.
* **Service principal client secret (optional)** → the OAuth secret of the service principal.
When the client secret is set, that connection authenticates with the secret only; the federation settings are not used for it. Leave the field empty to keep using federation. When you edit a connection, the field is empty even when a secret is stored, and leaving it empty keeps the stored secret; see [Switch a connection back to federation](#switch-a-connection-back-to-federation) to remove it. Syntho only uses a secret entered on a connection: a `DATABRICKS_CLIENT_SECRET` environment variable is ignored. If Databricks rejects the client ID or secret, the connection test reports it on the **Service principal client secret** field.
Security considerations for client secrets:
* **The secret is long-lived.** Anyone who has it can act as the service principal until it expires or is revoked, from anywhere the workspace is reachable. Syntho stores it encrypted and never returns it through its API or shows it in the connection form.
* **Rotate the secret.** Create secrets with a short lifetime, replace them on the connection before they expire, and revoke a secret as soon as it is no longer used or may have leaked.
* **Grant the least privilege.** Use a dedicated service principal for Syntho, and apply the same grant and entitlement restrictions as for federation.
#### Rotate the secret on a connection
Open the workspace's connection details, enter the new secret in **Service principal client secret**, test the connection and save. Then revoke the old secret in Databricks.
#### Switch a connection back to federation
1. Set up federation as described in [Configure Databricks](#configure-databricks) and [Configure Syntho](#configure-syntho).
2. Open the workspace's connection details.
3. Remove the stored secret: type any character in **Service principal client secret**, then delete it so the field is empty. Saving an emptied field removes the stored secret. Leaving the field untouched keeps the stored secret, and the connection keeps using it.
4. Decide which service principal federation authenticates as, using **Service principal client ID**:
* Keep the client ID to keep the same service principal. It then needs a federation policy.
* Replace it with the application ID of another service principal that has a federation policy.
* Clear it to use the client ID configured in the deployment (`DATABRICKS_CLIENT_ID`).
5. Test the connection and save.
6. Revoke the secret in Databricks.
## Supported Databricks versions
The table below provides an overview of the supported Databricks versions and their corresponding Apache Spark versions.
| Databricks Version | Spark Version |
| ------------------ | ------------- |
| 16.2 | 3.5.0 |
| 15.4 LTS | 3.5.0 |
| 14.3 LTS | 3.5.0 |
**Note:** Version 13 is no longer supported.
## Supported data types
The following table summarizes the current support limitations for various data types when using connectors with **Databricks**. It indicates what's supported per generator type.
| Data Type | AI-powered Generation | Mockers | Mask | Calculated Columns |
| -------------- | ------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------- |
| INT | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#discrete) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| SMALLINT | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#discrete) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| TINYINT | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#discrete) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| BIGINT | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#discrete) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-integer.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| DECIMAL | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#continuous) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-decimal.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-decimal.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| FLOAT | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#continuous) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-decimal.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-decimal.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| DOUBLE | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#continuous) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/numeric-decimal.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/numeric-decimal.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| STRING | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#categorical) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/text.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/text.md) | [True](/configure-a-data-generation-job/configure-column-settings/calculated-columns.md#supported-data-types) |
| BINARY | False | True\* | True\* | True\* |
| BOOLEAN | False | [True](/configure-a-data-generation-job/configure-column-settings/mockers/other.md) | False | True\* |
| DATE | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#datetime) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/datetime.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/datetime.md) | False |
| TIMESTAMP | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#datetime) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/datetime.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/datetime.md) | False |
| TIMESTAMP\_NTZ | [True](/configure-a-data-generation-job/configure-column-settings/ai-powered-generation.md#datetime) | [True](/configure-a-data-generation-job/configure-column-settings/mockers/datetime.md) | [True](/configure-a-data-generation-job/configure-column-settings/mask/datetime.md) | False |
| ARRAY | False | True\* | True\* | True\* |
| STRUCT | False | [True](/configure-a-data-generation-job/configure-column-settings/mockers/other.md#json) | False | False |
| MAP | False | True\* | True\* | True\* |
| VARIANT | False | True\* | True\* | True\* |
| OBJECT | False | True\* | True\* | True\* |
| ENUM | False | False | False | False |
{% hint style="info" %}
**\*** Some data types are not actively supported. Some generators may still show `True` for these fields. This means you can apply the generator, even though the type is not actively supported. Duplication is fully supported for these data types.
{% endhint %}
## Limitations
* When entering catalog, database, or schema names, use lowercase letters. Names containing capital letters must be entered in lowercase to ensure a proper connection.
* Schema, table, and column names containing single quotes (`'`) or backticks (\`) are not supported.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.syntho.ai/setup-workspaces/create-a-workspace/connect-to-a-database/databricks.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.