> For the complete documentation index, see [llms.txt](https://docs.syntho.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.syntho.ai/configure-a-data-generation-job/configure-column-settings/duplicate.md).
# Duplicate
Duplicate can be especially useful in the following situations:
1. When data does not contain personally identifiable information (PII) or sensitive elements, duplicating it allows for efficient replication without modification.
## Apply duplicate
1. Open your **Workspace**.
2. From the **Main hub** or **Table view** tab, select the column where you want to apply a generator.
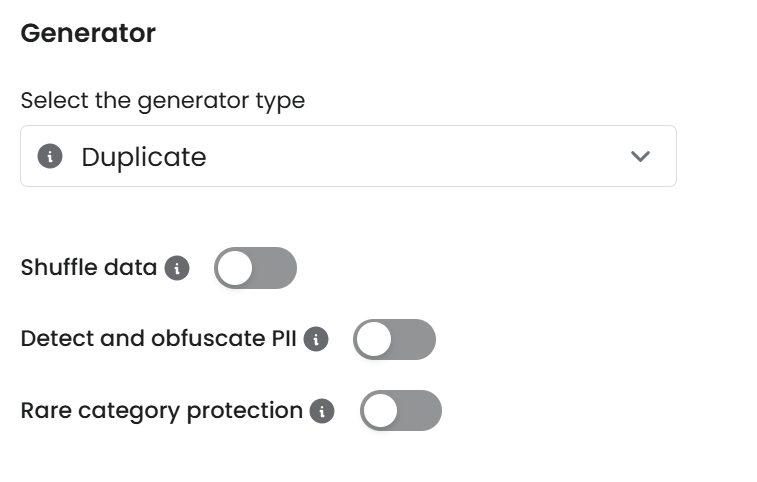
3. Under **Generator,** select **Duplicate** to copy the column from the source table to the destination table *as-is.*
4. Set the relevant duplicate parameters.
5. Select **Confirm**.
Selecting Duplicate in Generation Method panel
{% hint style="info" %}
**Note:** When you duplicate a column, the column is still used during the training process, as it can contain valuable information.
This means, however, that excluding columns *cannot* be used to to reduce hardware requirements or increase the speed of your synthetic data jobs.
{% endhint %}
## Text-specific masking
Text-specific masking options now live under **Mask** for text columns.
Use [Text](/configure-a-data-generation-job/configure-column-settings/mask/text.md) to configure:
* **Shuffle**
* [Rare Category Protection](/configure-a-data-generation-job/configure-column-settings/mask/text.md#rare-category-protection)
* [Free text PII obfuscation](/configure-a-data-generation-job/configure-column-settings/duplicate/automatic-pii-discovery-and-de-identification-in-free-text-columns.md)
## **Ordering and indexing considerations**
To ensure accurate ordering, please see [ordering and indexing considerations](/configure-a-data-generation-job/configure-column-settings/consistent-mapping.md#ordering-and-indexing-considerations).
## Supported data types
| Generator | Supported data types |
| --------- | --------------------------------------------------------------------------------------------- |
| Duplicate | Categorical, Continuous, Discrete, Datetime, Bytes, Bool, UUID, JSON, XML, Geo, Sets, Unknown |
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.syntho.ai/configure-a-data-generation-job/configure-column-settings/duplicate.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.